

I’ve been building a simulation of uplift modeling to understand something that sounds obvious but isn’t always easily implemented: a positive average treatment effect from an A/B test does not mean you should roll the change out to everyone. I built this to stress-test the standard playbook (run the test, check if the average lift is positive, ship it to 100%) against a more targeted alternative, in a simulation where I control the ground truth and can check my work.
The test case: the kind of ranking decision e-commerce sites, hotel-booking platforms, and airlines all face in some form. A treatment group sees pricier options pushed above the fold, instead of everyone seeing the same “best for anyone” default.
The Setup: A Nudge That Helps Some People and Hurts Others
Imagine a default ranking that’s “best for anyone”: not personalized to the individual searcher, just based on average purchase probability across everyone. This is a simplified example and simulation, not a description of any real system.
In the simulation, each search shows 10 listings above the fold, a mix of two property types: normal ($100/night) and premium ($150/night). The default ranking shows about 20% premium listings in that top 10, roughly whatever mix converts best on average. The treatment re-ranks the page so that mix becomes 50% premium.
Whether someone books, and what they book, depends on three things: the mix of what’s shown above the fold, their own underlying propensity to book at all, and how price-sensitive they are. That third piece is what makes the treatment a mixed bag:
Price-insensitive searchers see more premium options and are just as likely, or more likely, to book, often the pricier listing. Revenue per user goes up.
Price-sensitive searchers get some of the affordable listings they’d actually book pushed out of the top 10. Some of them don’t book at all. Revenue per user goes down.
I simulated 100,000 searchers under a randomized 50/50 experiment (the treatment arm sees the premium-forward ranking, the control arm sees the default), with realistic covariates: past bookings, historical price paid, device, market, trip type. One of them, historical price, correlates fairly strongly with price sensitivity; the rest barely do, and even the strongest one leaves real uncertainty behind. No single covariate fully reveals who’s price-sensitive; the model has to work for the rest. Baseline booking rate in the control group is about 37%, which I set deliberately to sit near the real baseline conversion rate in the field experiment I cite below, so the two examples are at least in the same neighborhood.
The Naive Decision: What the A/B Test Says
Averaged across the whole experiment, the treatment group generated $4.54 more revenue per user than the control group. That’s a real, positive lift. Under the standard playbook, this is the point where you ship it to everyone.
The Targeted Alternative
Instead, I trained a simple T-learner (two random forests, one fit on the treated arm and one on the control arm, both predicting revenue from the same covariates) using only the experiment data. The difference between the two forests’ predictions, for a given searcher, is that searcher’s estimated treatment effect: how much more (or less) revenue we’d expect from showing them the premium-forward ranking. The field-experiment paper I cite below uses more sophisticated tools than this. I picked the simplest thing that works for Part 1, and Part 2 gets into why the choice of method matters.
I then applied this model to a separate, held-out population of 200,000 searchers, the group about to see the actual rollout, and used it to decide who should see the premium-forward ranking: anyone with a positive predicted treatment effect, about 69% of this population. This idea, estimating what different assignment rules would have produced using the randomization itself, is the same logic that paper uses to evaluate its own targeting policies. The difference is that I also know each person’s true effect here, so I can check this decision rule against ground truth. No real company gets to do this; I’m using it here to verify the method works before trusting it.
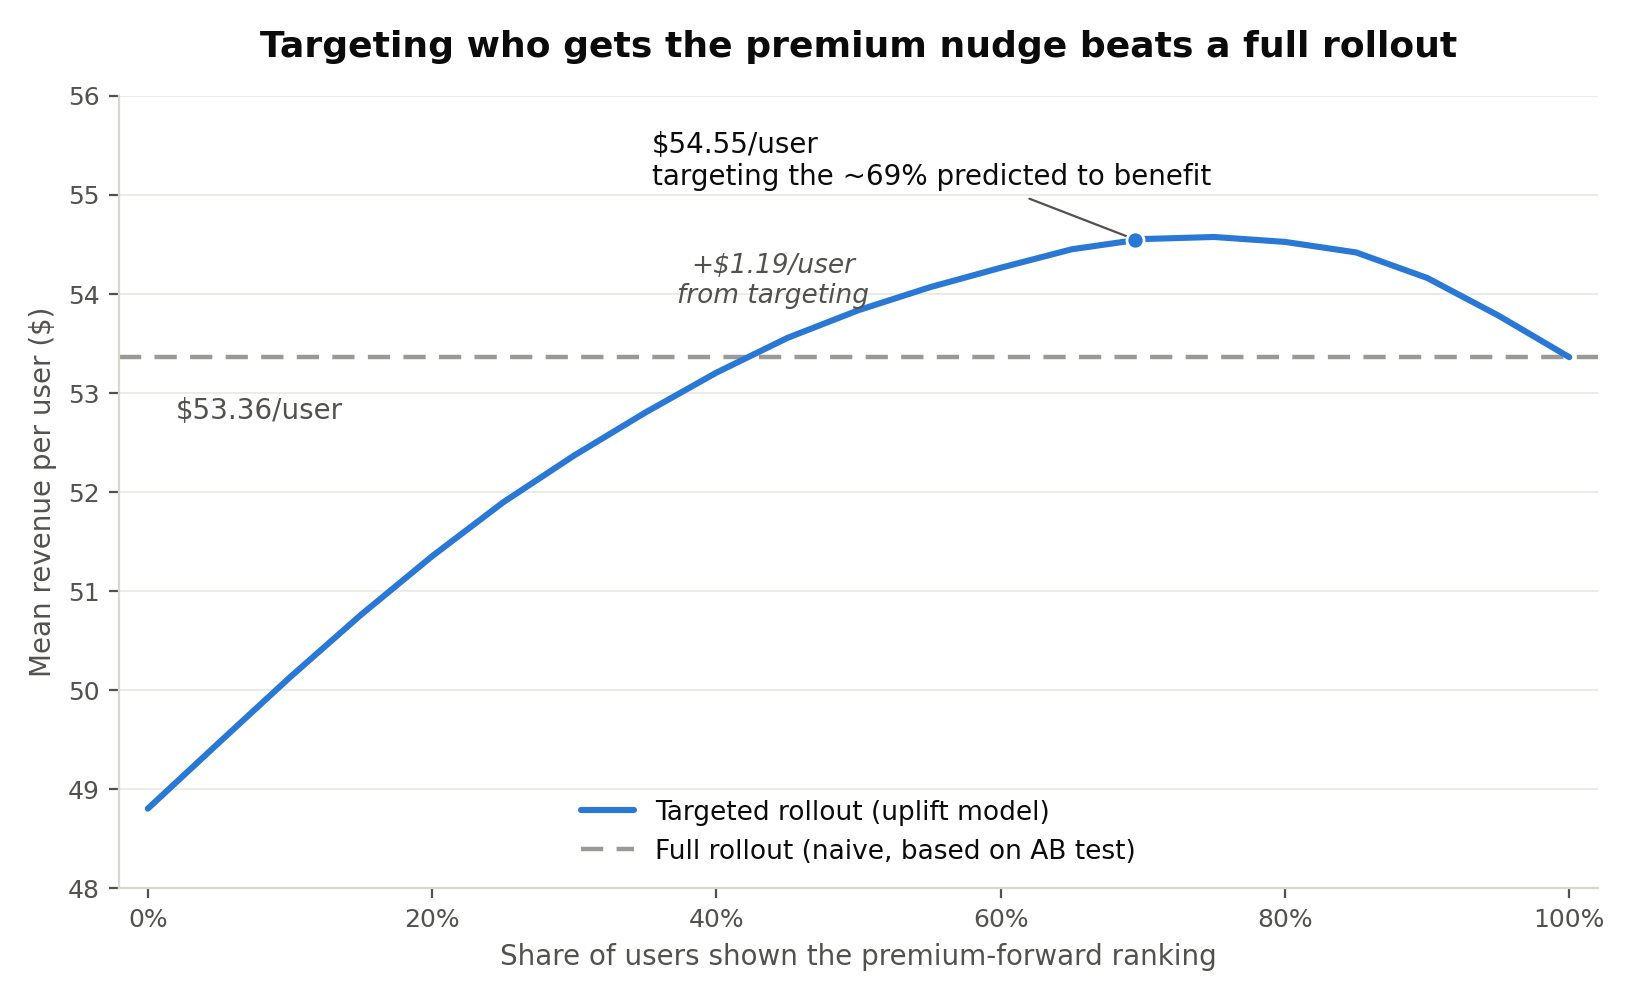
Full rollout generates $53.36 per user on average. Treating only the ~69% of users the model predicts will benefit generates $54.55 per user, a $1.19 improvement, about 2.2% more revenue than shipping to everyone. That gap exists because the other 31% has a negative predicted effect: showing them a pricier top-of-page pushes them toward not booking at all, and blanket rollout forces the treatment on them anyway.
Checking the Model Honestly
A single dollar figure is easy to overstate, so I checked how good the underlying predictions actually were, person by person, against the true effect I built into the simulation.
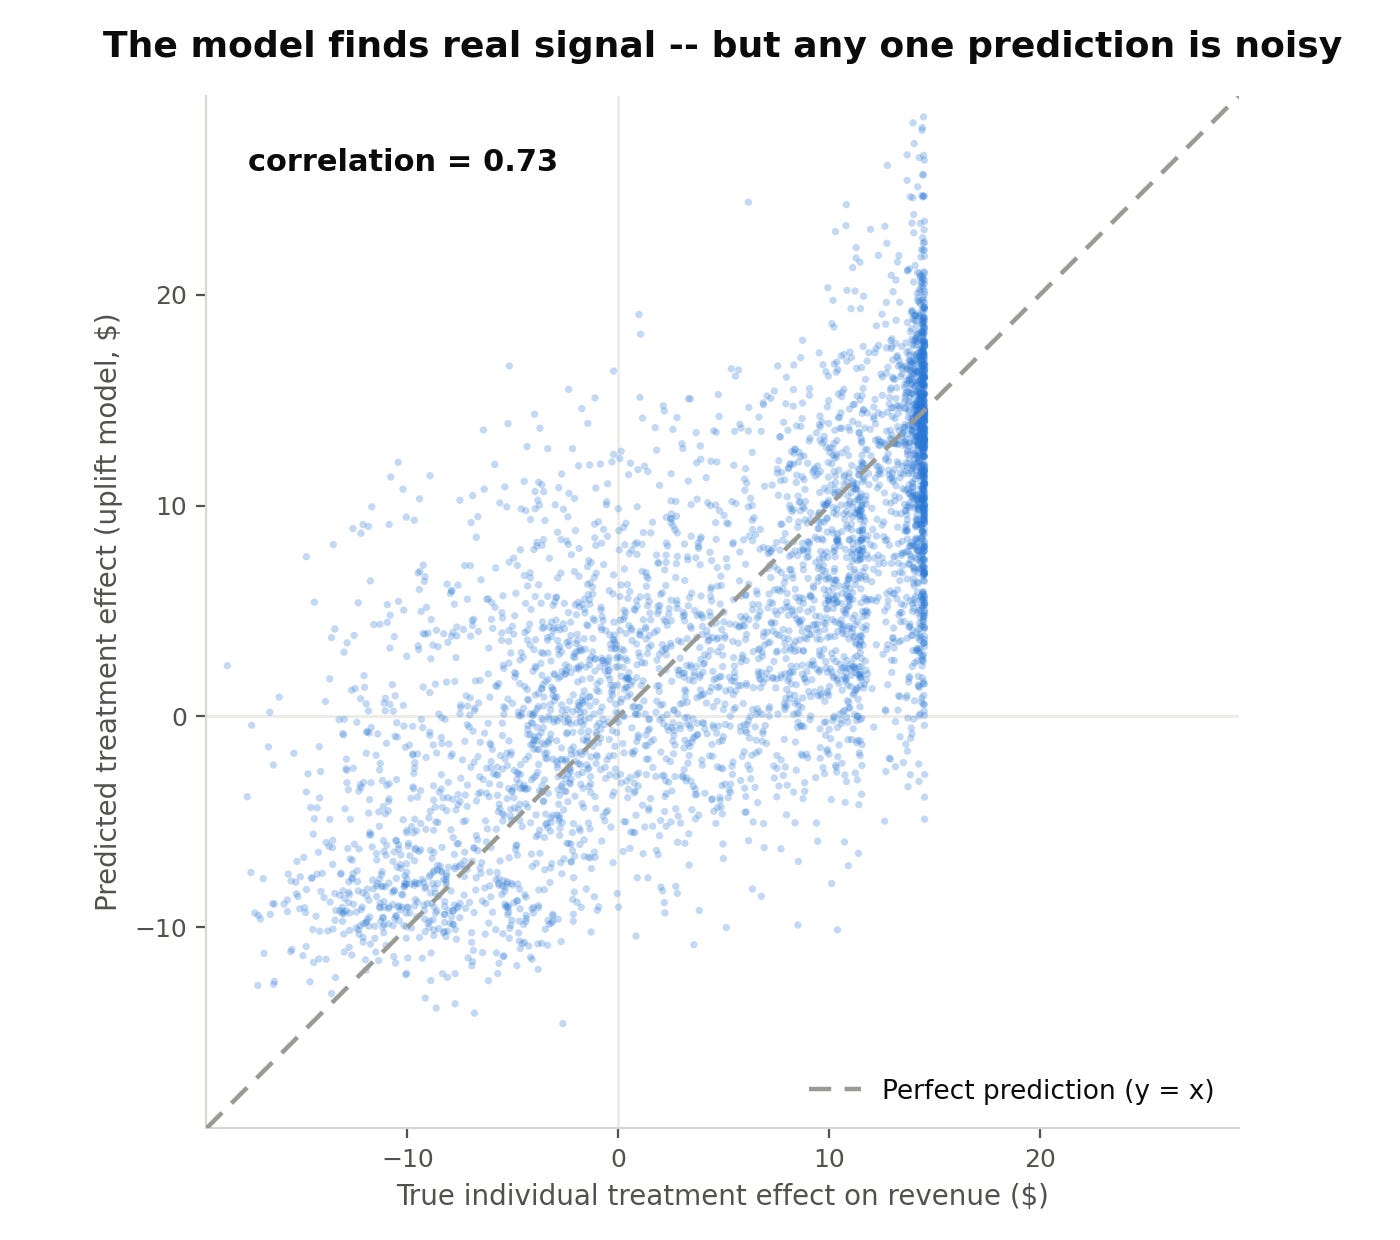
The correlation between predicted and true individual effects is 0.73. That’s real signal, enough to make the targeting decision above pay off, but it’s visibly noisy: any single person’s predicted effect could be off by a wide margin.
Part of why: nobody, including this model, ever observes both outcomes for the same searcher (what they’d do if shown the premium ranking, and what they’d do if shown the default). A model like this predicts by borrowing information from other searchers who share similar covariates, not by learning any individual’s actual response. This applies to every uplift model, not just this simple one, and it’s why the model is far more trustworthy in aggregate (ranking large groups and treating the predicted-positive slice) than it is for any single person’s exact predicted dollar figure. That distinction matters for how you’d actually deploy something like this, and it’s a big part of what makes picking a good uplift model harder than it looks, which is where Part 2 of this series goes.
This isn’t just a simulated toy problem, either. Athey, Keleher, and Spiess (2025) ran something structurally similar in a real field experiment: over 53,000 CUNY students were randomized into behaviorally-nudged reminders to renew their financial aid. Nudging everyone improved early filing by 6.4 percentage points on average over a 37% baseline, the same kind of clear, positive ATE that would trigger a full rollout under the naive playbook. Targeting half the students with their preferred policy still captured about 75% of that benefit.
That 75% figure needs a caveat, though. The paper is explicit that it found no evidence of negative treatment effects, and that sending reminders is cheap. The authors say directly that this limits the value of targeting: if a nudge is nearly free and never hurts anyone, capturing 75% of the benefit by treating half the students is a worse outcome than just treating everyone and capturing 100%. The actual case for targeting in a setting like theirs is a resource constraint, not harm avoidance. Texts and reminders still cost staff time and campaign budget, and if you can’t reach everyone, uplift modeling tells you who to reach first. This is a different, and just as common, reason to use uplift modeling than the one in my example above, where some users are made actively worse off if treated. Cost-constrained targeting and harm-avoidance targeting are two separate problems that happen to use the same tool.
Bottom Line
If you’re in a setting where a treatment plausibly helps some people and hurts others (not just helps everyone by different amounts, and not just costs money to deliver), a positive average effect from your A/B test only tells you whether to consider rolling something out. It doesn’t tell you who should get it. This simulation is a friendly environment: the treatment effect has real structure tied to observable behavior, and I get to check my answer against ground truth I built myself. Real data will be noisier and the model’s edge over blanket rollout will likely be smaller. But the direction of the result held up here: a simple model built from experiment data alone can beat “ship it to 100%.” It’s worth checking whether that holds in your own experiments before you roll the next positive test out to everyone.
I'm truly impressed by the high level and quality of the content you produce here and on other platforms. I work in market research, but I've become very interested in the whole area of experimentation because of your content. I would be very happy if someone in Brazil produced something similar.